CRM automation can be a growth engine. It can also be a mistake multiplier.
If your CRM data automation risks are rising, you usually do not notice at first. The system still “works.” Deals still move. Emails still send. But the hidden cost shows up everywhere else: duplicated accounts, wrong contact owners, broken routing, and service agents apologizing for stuff your company did not mean to do.
This is why customer data scaling issues become an enterprise problem fast. As you add integrations, workflows, AI features, and more users, small inaccuracies spread wider and faster. That pushes enterprise data quality management from a “nice-to-have” into a board-level risk conversation. Gartner has even estimated that poor data quality costs organizations $12.9 million per year on average.
If you are in a late-stage CRM system evaluation, here is the uncomfortable question: is your stack improving data quality, or simply distributing errors more efficiently? A real customer data accuracy strategy starts by fixing the inputs and rules before you scale the outputs.
Related Articles
What “Bad Data Automation” Actually Looks Like in the Wild
Bad CRM data is rarely a single issue. It is usually a pattern.
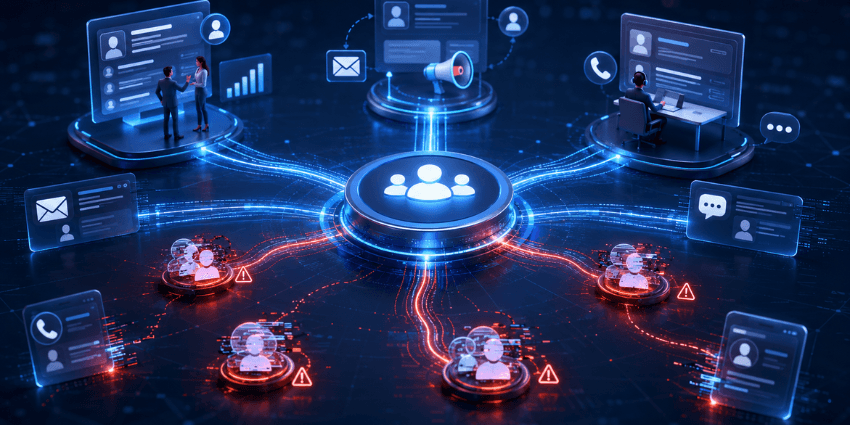
One team imports a list with messy fields. Another team creates new records because search feels slow. Someone builds an automation rule that assumes every “Company” is unique. Then marketing syncs the CRM to an email platform. Support syncs it to the ticketing tool. Finance connects ERP. Suddenly, one duplicate becomes five systems arguing about the “real” customer.
That is why this problem behaves like multiplication. Every integration and automation increases the blast radius.
How Does CRM Automation Amplify Bad Data?
Automation does not “create” bad data. It locks it in.
A workflow that assigns leads based on industry will keep doing that, even if industry values are inconsistent. A routing rule will keep sending cases to the wrong queue, if customer tier is wrong. A renewal forecast will keep inflating, if accounts are duplicated.
Automation also creates “confidence theater.” People assume machine-driven outputs are correct. They stop double-checking. That is when errors become policy.
If you are evaluating CRM platforms or automation layers, ask a blunt question: Which fields do our most important automations trust? Those fields should be treated like production infrastructure.
What Happens When Inaccurate Data Scales Across Systems?
At scale, inaccurate CRM data hurts four areas at once:
Sales loses time and trust. Reps chase ghosts, or contact the wrong person. Marketing burns budget. Targeting gets fuzzy. Attribution becomes unreliable. Service creates friction. Agents do not have clean context. Customers repeat themselves. Leadership gets false visibility. Dashboards look precise, but they are not accurate.
The cost is not only operational. It is reputational. Customers feel it.
And the bigger your business, the more expensive the cleanup becomes. Gartner’s data-quality cost estimate is a useful reminder here: this is not a small problem.
Where Do CRM Integrations Introduce Data Errors?
Most integration errors come from three common places:
Mapping and transformation. Fields do not match cleanly. Values get truncated or normalized badly. Identity resolution. Two systems disagree on what “one customer” means. Timing and sync logic. Updates arrive in the wrong order, or not at all.
Integration vendors position connectivity as a business unlock, and they are right. But integration also increases your need for governance, stewardship, and clear “golden record” logic. Informatica describes master data management as building authoritative records by consolidating, matching, and maintaining accurate master data.
If that sounds heavy, here is the plain-English version: pick the system that “wins” for each critical entity, and document it. Then enforce it.